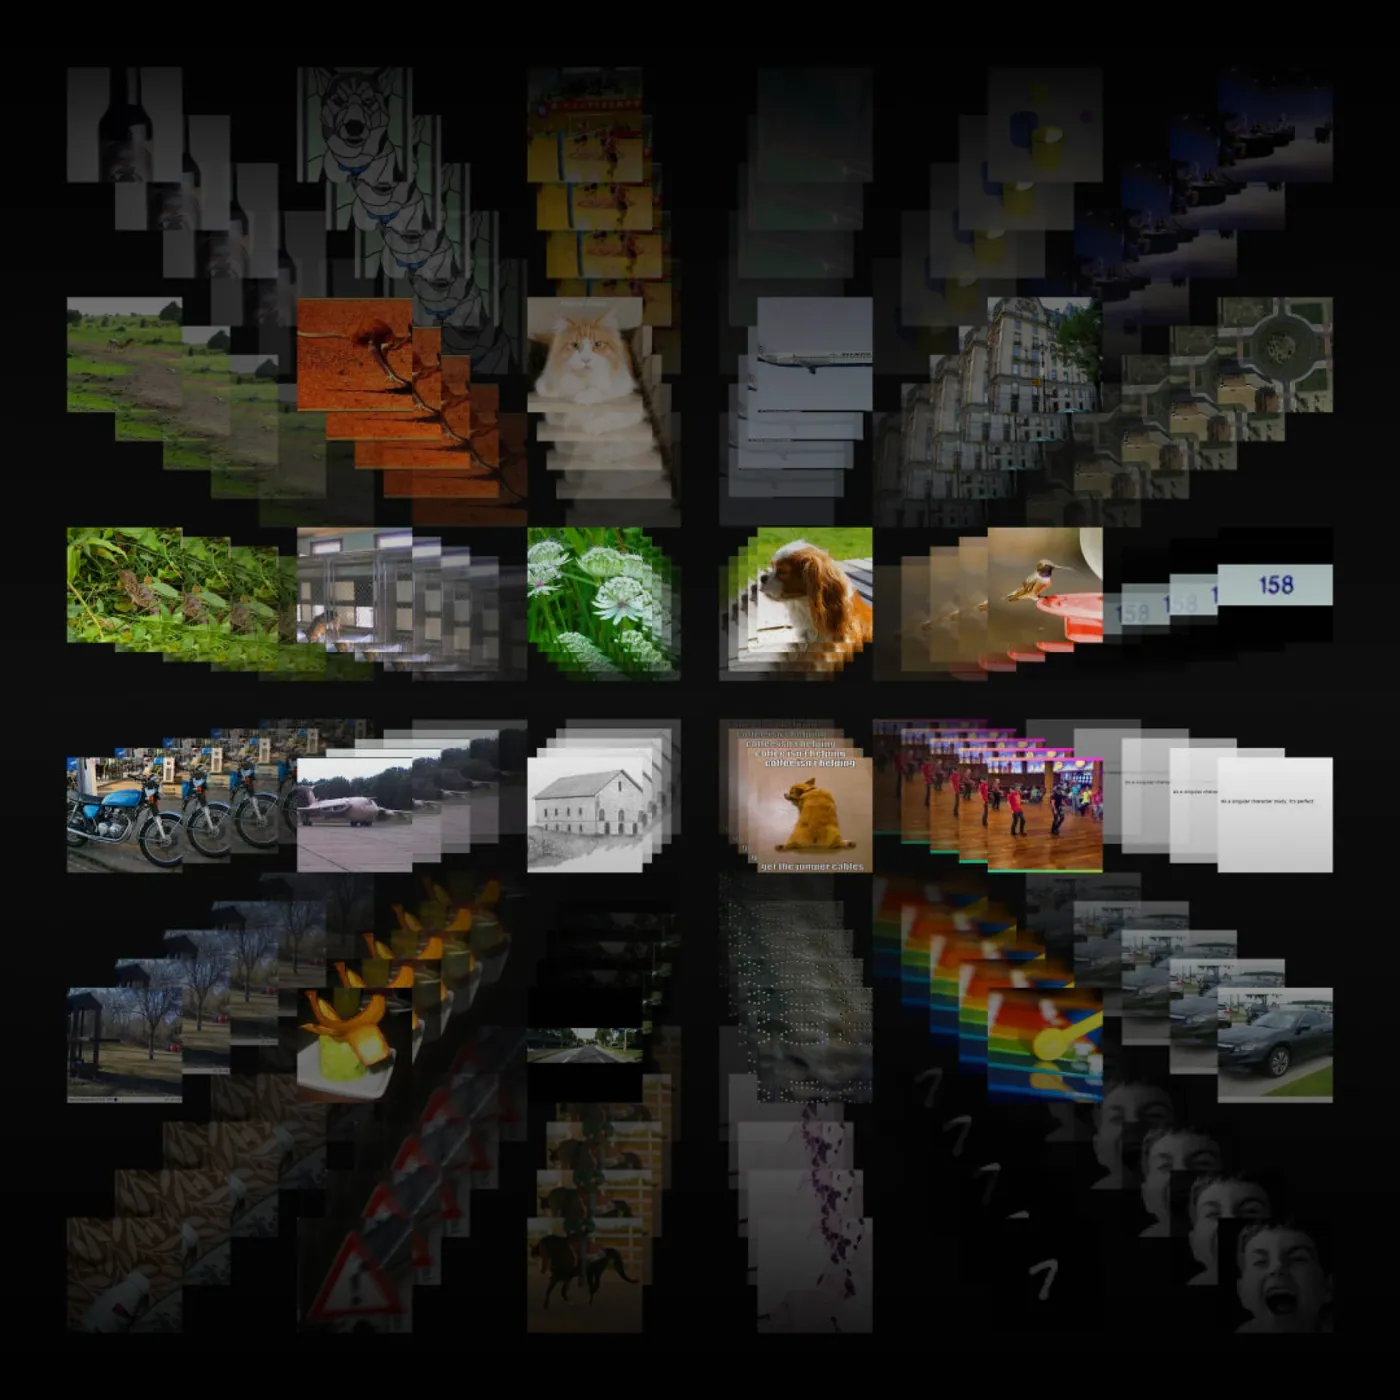
This post from OpenAI introduces CLIP, a powerful AI model that connects visual and textual data.
With CLIP, images and text can be embedded in the same space, enabling capabilities such as:
- Image classification without task-specific training
- Content moderation powered by multimodal understanding
- Image search based on natural language queries
CLIP demonstrates a new direction and vast potential for AI at the intersection of vision and language.
Reference: OpenAI CLIP Blog