 Products & Services
AI-Assisted Data Labelling
Let the model do the easy labels. People only check the hard ones.
How it works
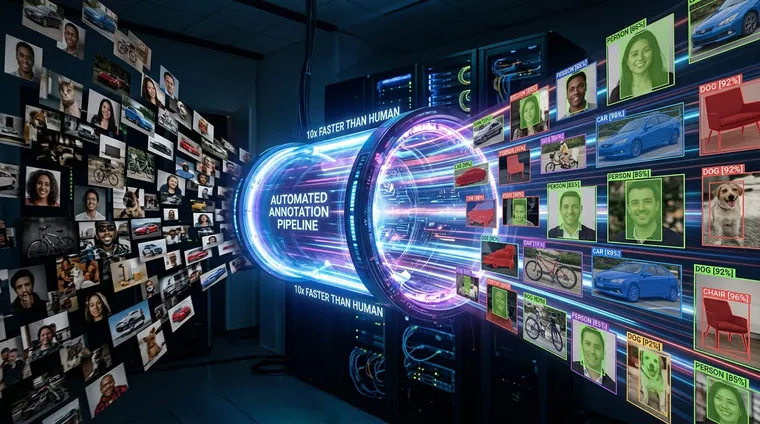
AI makes the first pass
A model starts on your images or video with very few examples.
People check the hard ones
Confident results go through. Unclear ones go to a person.
Every version is recorded
You always know which dataset trained which model.
Illustration only. Names and figures are made up.
Read the full description
A custom vision model is an AI trained to recognize things in pictures. It is only as good as its labelled data. Labelled data means pictures where someone has marked what is in them. Labelling by hand is the slow, costly part. Teams spend weeks drawing boxes and outlines. And the quality still varies from person to person.
We set up an AI-assisted labelling process. A model makes the first pass on your images or video. It uses zero-shot or few-shot methods, so it can start with very few examples. Confident results go straight through. Unclear ones are sent to a person for review. Every reviewed label is checked and versioned, which means each version is saved and recorded. So you always know which dataset trained which model.
You get a clean dataset with version records. If needed, you also get a trained model. It comes with its training settings and instructions to repeat the training. For projects inside China, the data and training stay in China.
What is included
AI makes the first pass
Zero-shot and few-shot methods label images and video before a person touches them.
People review only unclear cases
Confident labels pass through. Unclear ones are flagged for a person to review.
Boxes, outlines and segments
Supports bounding boxes, which are boxes drawn around each object. Also supports detailed segmentation for complex parts and scenes. Segmentation means marking which part of the picture is which.
Quality checks built in
Labels go through a review and quality check before they enter the training set. The training set is the data the model learns from.
Versioned datasets
Every version of the dataset is recorded. So any model can be traced back to the data it learned from.
From data to model
Collection, cleaning, labelling, training, evaluation (testing) and deployment (putting it to use), all in one chain.
Key strengths
You can retrain it yourself
We hand over the model weights, which hold what the model has learned. We also hand over the training settings and step-by-step instructions. With these, you can repeat the training on another machine.
Data stays where it should
For projects in China, training runs on computers inside China. The data does not leave the country.
Results you can measure
We use an offline test set plus live monitoring. A test set is a fixed group of examples kept aside for testing. So 'better' is shown with numbers.
You own the result
Project results and IP (intellectual property, meaning ownership of what was created) are transferred to the client under the contract.
In pictures
What we need from you
Representative examples, labels where available, data-use permissions and the cost of a wrong result.
Deliverables
- A reviewed dataset and labelling guide
- A baseline comparison and independent evaluation report
- A model or adaptation only when evaluation supports it
How it is accepted
Agree the evaluation split and error categories before training; compare against a simpler baseline on unseen examples.
Start with one small pilot.
Tell us the task. We will say whether it is worth doing.